This blog contains experience gained over the years of implementing (and de-implementing) large scale IT applications/software.

Encrypting HANA Data Volumes

Out of the box, the HANA database is not encrypted.
For those businesses that demand encryption, from within HANA Studio you can activate the encryption of the HANA data volumes.
The HANA documentation supplied with SPS7, suggests that the recommended approach is to encrypt the data volumes as part of the HANA installation process.  This is due to the “Copy-on-write” method used to persist data on disk.  An already used database may still have unencrypted data pages in it, even after encryption is enabled.

You should note that the words “data volumes” means the location of the database files for the indexserver and the statistics server, which is usually something like “/hana/data/<SID>/mnt0000<n>/hdb0000<n>/*.dat”.

Tip: You can check which values for “<n>” in the above, will be used, by checking the “Landscape Overview” tab and the “Volumes” tab within that.

Prerequisites:
– SAP recommend changing the SSFS encryption key after installation of the HANA system.  This key is used to store the data volume encryption key and others.
– Disk space of the data volume areas (we discuss this below anyway).
– Take a cold backup of the HANA DB area and config files.
– Access to the HANA Studio (you can do this with SQL access and hdbsql, but I don’t show this).

Let’s begin:

From within HANA Studio, open the “Security” tab and navigate to the “Data Volume Encryption” tab.
You will notice that encryption is not already enabled.
Tick the “Activate encryption of data volumes” tick box, then click the “Execute” button:

HANA volume encryption activation

HANA data volume encryption execute

The encryption process will start immediately (“Encryption Pending” then “Encryption Running”):

HANA volume encryption pending

The status is updated when each server process finishes:

HANA volume encryption running

Once the encryption process is completed successfully, the tick box is enabled again for you to be able to de-encrypt the volumes should you wish to reverse the process:

HANA volume encryption encrypted

My small (empty) HANA DB @ sps7, took approximately 10 minutes to encrypt.
The data volume sizes increased as part of the encryption process.
The indexserver data volume went from 324MB used to 341MB used:

HANA volume encryption indexserver size

HANA volume encryption indexserver size

Of more importance is the dramatic increase in the allocated (Total Size).
It’s gone from 513MB to 896MB!  You will need to be aware of the disk space you may need before enabling encryption.

The statistics server is smaller and went from 80MB used to 101MB used:
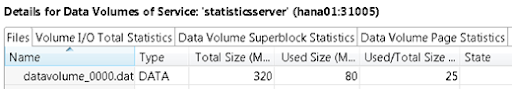
Snap668 2014-06-26, 11_26_17

image

Again, notice that we’ve got an increased allocation from 320MB to 400MB.

Validate the encryption status using an SQL console:

SELECT * FROM M_PERSISTENCE_ENCRYPTION_STATUS;

image

What are the implications for encryption?

Well, the data volumes have been encrypted, but we’ve not seen anything about encrypting the logs or the backups.
Also, to preserve the performance of the HANA system in memory, the data is decrypted when read from the disk into memory.

Is encrypting the HANA DB transaction logs feasible?  Probably not.  There are various whitepapers detailing the issues of encryption of data stored on SSDs.  Since the majority of high performance appliance resellers use SSDs for the HANA DB transaction logs, the use of software layer encryption on SSDs is not worth the effort and would probably reduce the performance of the database.  Instead, using the SSD hardware layer encryption may prove useable, but this is only worth while if you think that the SSD could be physically stolen.  SSD hardware encryption doesn’t prevent an intruder at the O/S level from seeing the data.

Is encrypting the HANA DB backups (data and logs) feasible?  Yes this is definitely something that should be employed.  There are 3rd party backup tools that will take a copy of the HANA backup files, then encrypt and store elsewhere.  But these tools may not support secure wipe, so the disk location of the backup files would potentially still contain the data.  Using backup tools certified for SAP with the BackInt interface would be better, since the data doesn’t touch the disks, it’s piped straight to the backup device via the “network”.

There is possibly some slight performance impact from encrypting the data volumes.  The data files are written to at least every 5 minutes.  They are also read from during HANA start up.  These I/O operations will be the same speed as they were before, except there will be some additional software routines involved to perform the encryption, which will use slightly more memory and mean a slight delay between the data being read/written to/from the disk.

Be aware of bugs in the backup/restore process.
I’ve seen mention of bugs in other software products where an encrypted backup is void due to a software bug.  Ensure that you test your solution thoroughly.

SAP recommend that you change the Page Encryption Key (used to encrypt the data volumes) regularly as per your organisations standards.  This may yet again increase the allocated size.

Summary:
– Data volume encryption is easy and fast in HANA.  There’s not really any reason to not implement it.  Beware of implementing in an already populated database and ensure you change the keys regularly.
– Backups and transaction log volumes are not encrypted and for the logs there’s a good reason why you may not want to.
– Performance in certain scenarios could be affected slightly.
– You should attempt to implement a supported Backint capable backup product with encryption, since the backups with this method don’t touch the unencrypted disks.
– Encryption can be performed and validated at the SQL command level.
– Be aware that data volume encryption in HANA will require more disk space to be allocated to the data volumes, increasing the footprint of the HANA database by as much as 50%.

SAP DBCO Connection Without TNSNAMES

In order to create an external database connection to another database, so that an ABAP program can access it, you normally create the connection details in transaction DBCO.

However, if you use the ST04 transaction, it provides additional fields where you can enter the connection details such as Oracle listener port number, which will allow you to construct a connection string which will not require an entry in the server’s TNSNAMES.ora file.

SAP Unicode Conversion MAXDOP Parallelism on MS SQL Server

When performing a Unicode conversion of an SAP system running on MS SQL Server database, you get pointed to the Unicode Collection Note 1319517.
This note points to a MS SQL Server specific note (Note 1054852 – Recommendations for migrations to MS SQL Server)  which covers a couple of different scenarios, such as moving to SQL Server from another database provider, or just performing an R3load export/import (like me) to the same platform.

Now from experience, I know that the R3load import is actually pretty quick (especially on Oracle with DIRECTPATH).  What takes the time is the index creation afterwards.  Lots of scanning and I/O needs to be done.  This is where you waste time, and where you could save time.
The note 1054852 mentions the use of the MAXDOP (Maximum Degree of Parallelism) SQL Server parameter that could benefit any subsequent index creation/rebuild tasks performed during an R3load import.
The recommendation in note 1054852 is to change the MAXDOP from the SAP recommended setting of 1, to 4 for the entire SQL Server instance.  NOTE: The maximum MAXDOP in 2008R2 is 1024 (see here and SAP note 1654613).
This is the “hammer” approach and should be used with caution.  There is a nice blog here on the use of MAXDOP with SQL Server.  The blog shows how setting this to a value greater than 1 can actually increase fragmentation.  This is completely understandable.  However, the reader must note that the fragmentation is only an issue if the index is specifically set with ALLOW_PAGE_LOCKS to “OFF” (the default in 2008R2/2012 is “ON” (see syntax here)! ).
There is another blog article that shows how this fragmentation problem is overcome by setting the ALLOW_PAGE_LOCKS option.  The article states that by default this is “ON”.  However, according to Microsoft KB 2292737, the default is “OFF” by design. 
So which is it?  In fact, the MS syntax for “ALTER INDEX” specifically states that it is not possible to reorganise an index with ALLOW_PAGE_LOCKS set to “OFF”.

Here’s how to check the value of the ALLOW_PAGE_LOCKS setting for an index (there is no global setting):


use <SAP DB>
go

select name,type,allow_page_locks from sys.indexes
where allow_page_locks != 1
order by 1;


And the results…  well, some of the largest SAP tables in my system have their indexes set with ALLOW_PAGE_LOCKS to “OFF“.  Great!

NAME
TYPE
ALLOW_PAGE_LOCKS
ARFCRDATA~0
1
0
ARFCSDATA~0
1
0
COVREF~0
1
0
COVREF~001
2
0
COVREF~002
2
0
D010INC~0
1
0
D010INC~1
2
0
D010TAB~0
1
0
D010TAB~1
2
0
EDI40~0
1
0
EDIDC~0
1
0
EDIDC~1
2
0
EDIDC~2
2
0
EDIDC~3
2
0
EDIDC~4
2
0
EDIDS~0
1
0
EDIDS~1
2
0
EDIDS~2
2
0
REPOLOAD~0
1
0
REPOSRC~0
1
0
REPOSRC~SPM
2
0
TRFCQIN~0
1
0
TRFCQIN~1
2
0
TRFCQIN~2
2
0
TRFCQIN~3
2
0
TRFCQIN~4
2
0
TRFCQIN~5
2
0
TRFCQIN~6
2
0
TRFCQOUT~0
1
0
TRFCQOUT~1
2
0
TRFCQOUT~2
2
0
TRFCQOUT~3
2
0
TRFCQOUT~4
2
0
TRFCQOUT~5
2
0
TRFCQOUT~6
2
0
VBDATA~0
1
0
VBHDR~0
1
0
VBMOD~0
1
0

I can understand the VB* tables might not want index locking and this is also hinted at in the older SAP R/3 Performance Tuning Guide for Microsoft SQL Server 7.0 web page.  However, where did the other tables come from?
I took a look on SAP Notes but I was unable to find anything definitive.  The system I was working on was recently copied and used SWDM (SAP Software Deployment Manager) to perform the post-copy steps, so it’s possible that the indexes were automatically adjusted (ALTER’d) to try and ensure a consistent approach.
What to do next?  Well, some of those tables can be ignored since they are supposed to have ALLOW_PAGE_LOCKS set to “OFF”, some, like REPOLOAD are re-populated only during a system-copy with R3 tools (e.g. Unicode conversion), so you could try adjusting the setting during the R3load import. 
The others, well in theory you would try to minimise data in those tables (like TRFC*) before you perform a Unicode conversion, so the indexes wouldn’t be massive anyway.

At the end of the day, all we are talking about here is a little fragmentation.  So let’s move on.

Let’s go back to the MAXDOP setting recommendation mentioned in SAP note 1054852. 
Now, my system happens to be a BW type system (it’s actually SEM, but this is just BW in disguise), so I found SAP Note 1654613 – SQL Server Parallelism for SAP BW which suggests that for SAP BW systems, you can now manage the MAXDOP parameter settings in table RSADMIN through report SAP_RSADMIN_MAINTAIN by setting parameters MSS_MAXDOP_QUERY, MSS_MAXDOP_<cubename> and MSS_MAXDOP_INDEXING.
The note 1654613 also goes on to say that by applying the note corrections (or the related support package stacks) the default MAXDOP for BW queries is set to 2, and for (process chain) index creations is set to 8.
Aha! 
So the Unicode collection note’s setting of 4, could actually contradict the setting of 8 in BW systems!
The note 1654613 also states that you may increase the MAXDOP for queries to more than 4, but this depends on the number of worker threads configured in your SQL Server instance.
The worker threads setting in my SQL Server 2008R2 instance was set to “0”, which means the number is dynamically calculated (see here).

You can use the sp_configure procedure to check your setting:

sp_configure @configname='max worker threads';

You can query the current number of threads (thanks to https://blogs.msdn.com/b/boduff/archive/2008/05/17/configuring-max-worker-threads-in-sql-2005.aspx):

select count(*) from sys.dm_os_threads;

My idle database was using 50 threads on a VMWare VM with 4 processors.  So I guess I could increase the MAXDOP for queries permanently in my BW (SEM) system.

You should also note the setting MSS_MAXDOP_INDEXING = 0 means that all available threads will be used during (process chain) index creation.

Summary:
We are advised to set MAXDOP to 4 when moving an SQL Server database or performing a system-copy or Unicode conversion. 
However, more detailed analysis has shown that for BW systems specifically, we can potentially adjust the MAXDOP setting even higher than 4 during our R3load import, to ensure that we make the best use of the available CPU. 
This is underlined by the fact that defaults within the BW system are sometimes higher than the recommended setting of 4.
Therefore, I will be trying out a value of 12 (default of 8 for index creation + 50%) in my Unicode conversion:

sp_configure 'max degree of parallelism', 12;
reconfigure with override

SAP Netweaver 731 Oracle Create DB Statement

By default, when you use the Software Provisioning Manager (SWPM) to create a new NW731 Oracle database, it will generate and run an Oracle “CREATE DATABASE” statement as follows:

SQL> CREATE DATABASE DB1 CONTROLFILE REUSE 
MAXLOGFILES 255
MAXLOGMEMBERS 3
MAXLOGHISTORY 1000
MAXDATAFILES 1000
MAXINSTANCES 50
NOARCHIVELOG
CHARACTER SET UTF8
NATIONAL CHARACTER SET UTF8
DATAFILE '/oracle/DB1/sapdata1/system_1/system.data1' SIZE 350M REUSE AUTOEXTEND ON NEXT 20M MAXSIZE 10000M EXTENT MANAGEMENT LOCAL
DEFAULT TEMPORARY TABLESPACE PSAPTEMP TEMPFILE '/oracle/DB1/sapdata1/temp_1/temp.data1' SIZE 50M REUSE
AUTOEXTEND ON NEXT 20M MAXSIZE 10000M
UNDO TABLESPACE PSAPUNDO DATAFILE '/oracle/DB1/sapdata1/undo_1/undo.data1' SIZE 100M REUSE AUTOEXTEND ON NEXT 20M MAXSIZE 10000M
SYSAUX DATAFILE '/oracle/DB1/sapdata1/sysaux_1/sysaux.data1' SIZE 200M REUSE AUTOEXTEND ON NEXT 20M MAXSIZE 10000M
LOGFILE GROUP 1 ('/oracle/DB1/origlogA/log_g11m1.dbf') SIZE 200M  REUSE ,
GROUP 2 ('/oracle/DB1/origlogA/log_g12m1.dbf') SIZE 200M  REUSE ;


Notice that both the character set and national character set are UTF8.

HowTo: Use Oracle BBED to adjust DB Name in File Headers

HowTo: Use BBED to hack the database SID in the datafiles if you’ve gone and got them all mixed during a “CREATE CONTROLFILE” operation.

WARNING: Using BBED is not supoprted by Oracle unless you are asked to use it by Oracle Support themselves.

Use UNIX vi to create a text file that contains a line number, followed by the file name for the DB files that need changing:

# cat <<EOF > filelist.txt
1 /db/ora/system/system1.dbf
2 /db/ora/data1/data1.dbf
3 /db/ora/index1/index1.dbf
EOF

Save the file as “filelist.txt”.

Launch bbed (blockedit) as the Oracle DB UNIX owner.
Change the text “NEWID” for your new DB name in the “modify” line below.

$ bbed
BBED> set listfile 'filelist.txt'
BBED> set mode edit

# Dump the current block value for datafile #1 in your list file.
# exmaple: BBED> dump /v dba <file#>,<block> …

BBED> dump /v dba 1,1 offset 32 count 16

Make the swap:

BBED> modify /c NEWID file 1 block 1 offset 32

The checksum is now invalid:

BBED> sum file 1 block 1

Force save the new checksum:

BBED> sum file 1 block 1 apply

Verify the block:

BBED> verify file 1 block 1

Once you’ve done all your files:

BBED> quit;

Start the database with the CREATE CONTROLFILE SET DATABASE “NEWID”…